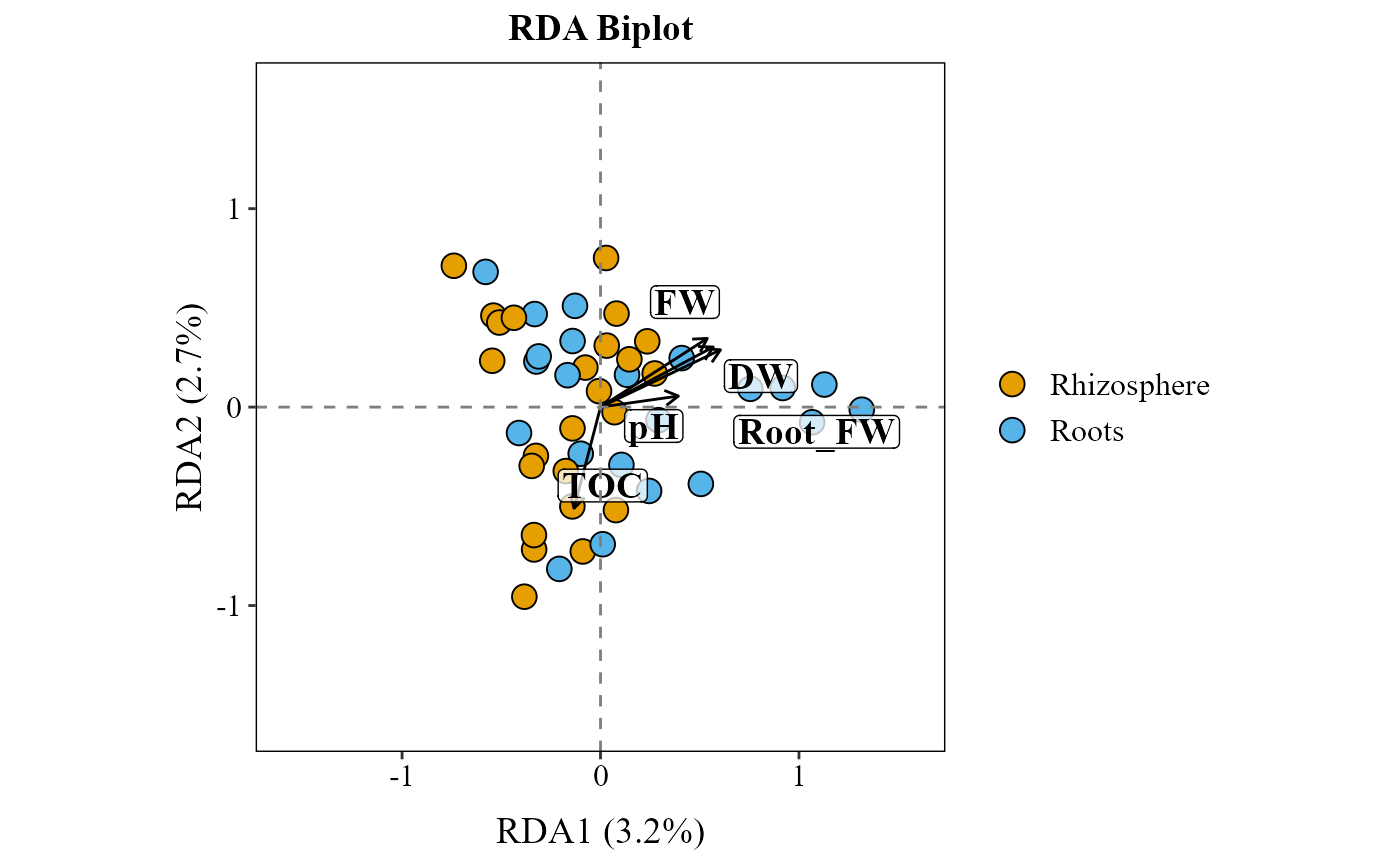
Performs a Canonical Correspondence Analysis (CCA) or a Redundancy Analysis (RDA) of the abundance table constrained by environmental variables, and plots the samples and the environmental vectors as a biplot.
Usage
cca_rda_biplot(
  table,
  env_data = NULL,
  env_vars,
  method = "hell",
  metadata,
  group_col = NULL,
  group_colors = NULL,
  legend_title = NULL,
  scale_env = TRUE,
  pval_threshold = 0.05,
  p_adjust_method = "none",
  show_all_env_vectors = FALSE,
  analysis = "CCA",
  scale_arrows = 1,
  title = "auto",
  save_table = FALSE,
  table_filename = "cca_rda_scores.txt"
)
Arguments
- table
A data frame with taxa in rows and samples in columns. The last column must be named
taxonomy, containing full taxonomic strings.- env_data
Optional data frame of environmental variables, with row names matching the sample names in
table. DefaultNULL: the variables named inenv_varsare taken frommetadata. Use it only when the variables are in a separate table.- env_vars
A character vector with the names of environmental variables (columns of
metadata, or ofenv_dataif given) to include in the analysis.- method
Character. Transformation of the abundances, passed to
vegan::decostand(). Default"hell"(Hellinger).- metadata
A data frame containing sample metadata. Its first column must hold the sample IDs (the column names of
table). The environmental variables can be columns ofmetadata(seeenv_vars).- group_col
Character. Name of the column in
metadatathat defines the groups. Used to color the samples. Optional;NULL(default) for no groups.- group_colors
Optional character vector of colors, one per group, named after the groups or in their order. If
NULL(default), the colorblind-friendly Okabe-Ito palette is used.- legend_title
Character. Title of the legend. If
NULL(default), the name ofgroup_colis used.- scale_env
Logical. If
TRUE(default), the environmental variables are scaled (without centering) before the analysis.- pval_threshold
Numeric. P-value cutoff (after
p_adjust_method) to draw only the significant environmental variables. Default0.05.- p_adjust_method
Character. Multiple-testing correction for the
vegan::envfit()p-values of the environmental variables, any method ofstats::p.adjust(). Default"none"(raw p-values), the usual choice with few variables.- show_all_env_vectors
Logical. If
TRUE, all the environmental variables are drawn, significant or not. DefaultFALSE.- analysis
Constrained ordination method:
"CCA"(default, Canonical Correspondence Analysis) or"RDA"(Redundancy Analysis). Case-insensitive.- scale_arrows
Numeric. Multiplies the length of the environmental arrows; it only changes how they are drawn. Default
1.- title
Character. Plot title.
"auto"(default) shows"CCA Biplot"or"RDA Biplot";NULLshows no title; any other text is used as the title.- save_table
Logical. If
TRUE, saves the sample scores and environmental vector loadings (one table, with atypecolumn:"site"or"vector") as a tab-delimited file. DefaultFALSE.- table_filename
Character. Name or path of the saved file (used when
save_table = TRUE). Default"cca_rda_scores.txt".
Value
A ggplot object with the biplot. The axis titles show the percentage of the variance (inertia) explained by each constrained axis.
Details
The p-values of the environmental vectors come from
vegan::envfit() permutations; call set.seed() before the
function to make them reproducible.
Examples
table_path <- system.file("extdata", "subset_table_bacteria.txt", package = "MicroBioMeta")
table <- read.delim(table_path, row.names = 1, check.names = FALSE)

metadata_path <- system.file("extdata", "subset_metadata_bacteria.txt", package = "MicroBioMeta")
metadata <- read.delim(metadata_path, check.names = FALSE)

# The environmental variables are columns of metadata, chosen with env_vars
cca_rda_biplot(
    table                = table,
    metadata             = metadata,
    env_vars             = c("pH", "TOC", "FW", "Root_FW", "DW"),
    analysis             = "RDA",
    show_all_env_vectors = TRUE,
    group_col            = "Location"
)