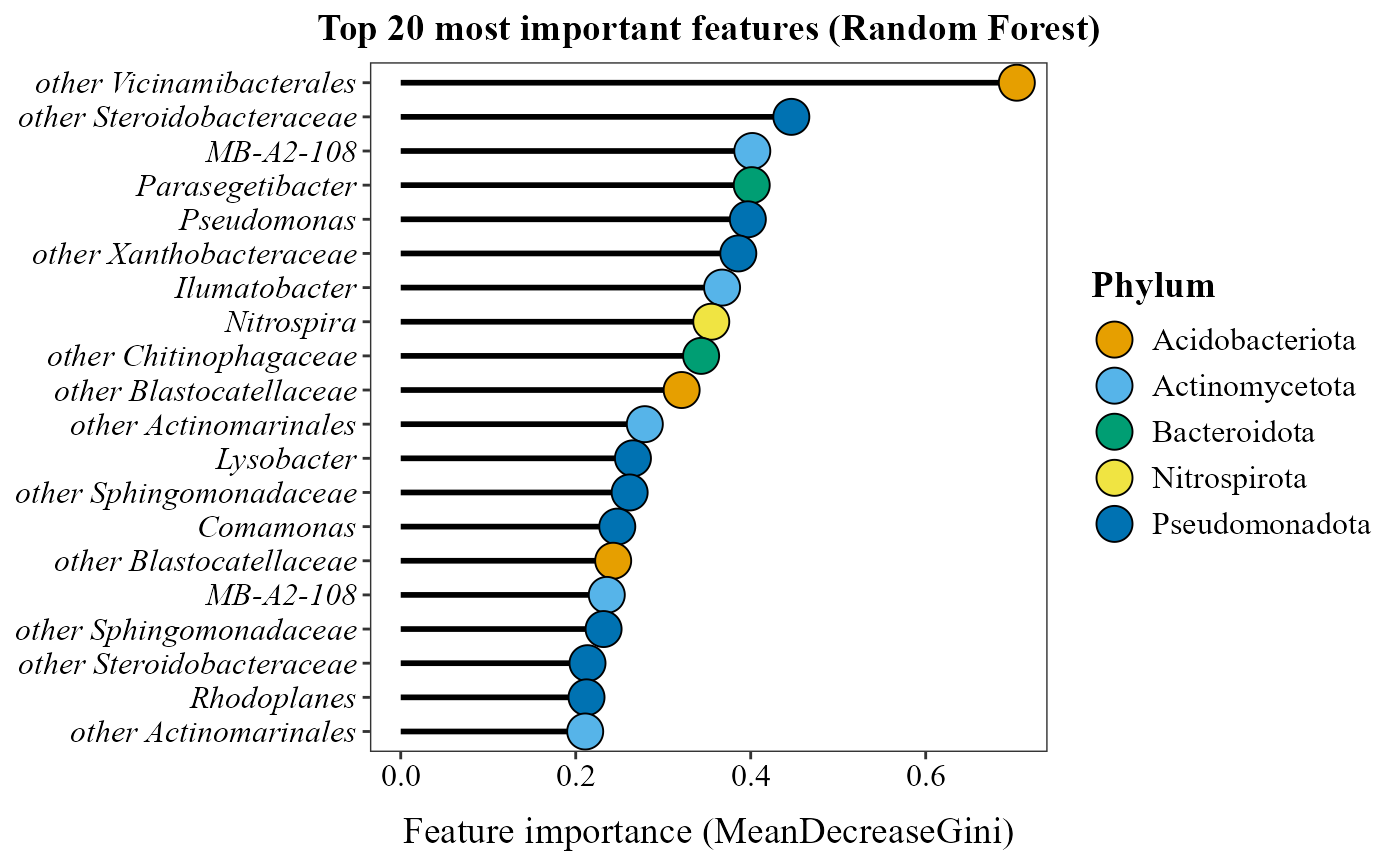
Random forest feature importance plot
Source:R/random_forest_lollipop_plot.R
random_forest_lollipop_plot.RdFits a random forest (randomForest) that predicts a metadata variable from the abundances, and plots the most important features as a lollipop plot colored by phylum.
Usage
random_forest_lollipop_plot(
  table,
  metadata,
  top_n = 15,
  size = 8,
  variable_to_predict,
  group_colors = NULL,
  title = NULL,
  save_table = FALSE,
  table_filename = "randomforest_importance.txt",
  x_axis_title = "Feature importance (MeanDecreaseGini)"
)
Arguments
- table
A data frame with taxa in rows and samples in columns. The last column must be named
taxonomy, containing full taxonomic strings.- metadata
A data frame containing sample metadata. Its first column must hold the sample IDs (the column names of
table).- top_n
Integer. Number of most important features to show. Default
15.- size
Numeric. Size of the lollipop points. Default
8.- variable_to_predict
Character. Name of the column in
metadatato predict (a categorical variable).- group_colors
Optional character vector of colors, one per phylum (recycled if shorter). If
NULL(default), the package palette is used.- title
Character. Plot title.
NULL(default) shows no title.- save_table
Logical. If
TRUE, saves the feature-importance table as a tab-delimited file. DefaultFALSE.- table_filename
Character. Name or path of the saved file (used when
save_table = TRUE). Default"randomforest_importance.txt".- x_axis_title
Character. Title of the x-axis (feature importance). Default
"Feature importance (MeanDecreaseGini)".
Details
The random forest is random; call set.seed() before the
function to make the result reproducible.
Examples
table_path <- system.file("extdata", "subset_table_bacteria.txt", package = "MicroBioMeta")
table <- read.delim(table_path, row.names = 1, check.names = FALSE)

metadata_path <- system.file("extdata", "subset_metadata_bacteria.txt", package = "MicroBioMeta")
metadata <- read.delim(metadata_path, check.names = FALSE)

random_forest_lollipop_plot(
    table               = table,
    metadata            = metadata,
    variable_to_predict = "Location",
    top_n               = 20,
    size                = 6
)